


Biography & Foundations
About Me
👋 Hi there! I'm Sushovan Saha — currently working as a founding AI Engineer at a Stealth Startup, building production-grade intelligent systems with deep focus on Large Language Models (LLMs), Generative AI, Voice Agents, Deep Learning, Natural Language Processing (NLP), and Computer Vision (CV).
🎓 I hold an M.Tech in Data Science from IIT Guwahati and I'm currently a Kaggle Notebook Expert with a strong inclination toward solving real-world challenges using intelligent systems.
Technical Competencies
Engineering Capabilities
- LLMs & Generative AI: Proficient in RAG, GraphRAG, Agentic RAG, MCP, LangChain, LangGraph, Google ADK, and building Agentic Workflows
- Voice Agents & Real-Time AI: Building end-to-end real-time Voice Agents using LiveKit, WebRTC, low-latency audio pipelines, and tool-augmented conversational agents
- Model Fine-Tuning & Post-Training (Reasoning & RL): Hands-on experience in fine-tuning models on custom datasets with SFT (Supervised Fine-Tuning) and GRPO (Group Relative Policy Optimization) on Qwen3.5 4B, leveraging HuggingFace, Unsloth, PyTorch, and PyTorch Lightning
- Applied ML & Deep Learning: End-to-end project experience across NLP, Computer Vision (CV), and Time Series domains
- Time Series & Forecasting: Statistical and deep learning models for trend analysis, predictive modeling, and demand Forecasting
- MLOps & Scalable ML Systems: Focus on production-grade pipelines, model deployment, and monitoring with MLflow
- API & Deployment: Experience in deploying models as APIs using FastAPI and deploying on cloud platforms like AWS and GCP
- CI/CD: Experience in setting up CI/CD pipelines using GitHub Actions
- Data Science: Experience in data analysis, statistical analysis, data visualization, and data preprocessing using Pandas, NumPy, Matplotlib, Seaborn, and Scikit-learn
Tooling & Platform Stack
Frameworks & Ecosystem
Beyond the Code
Personal Pursuits

AI Stock Research Agent
High-probability range breakouts, financial health diagnostics, and deep fundamental screening across NIFTY500 and MICROCAP250.
Harry Potter & Ancient Mythology
What secrets of the wizarding world shall we uncover?
Cross-examine Harry Potter lore, spells, Horcruxes, and Indian ancient epics via Pinecone vector retrieval
Autonomous Tour Planner
What’s on the agenda today?
Query live Airbnb accommodations via MCP and real-time weather forecasts to curate verified vacation itineraries
Real-Time Voice Agent
Ultra-low-latency conversational intelligence with full-duplex audio streaming and dynamic tool dispatch.
YOLO Object Detection
State-of-the-art brand mark localization and real-time bounding box prediction on custom imagery.
🚀 YOLOv8.1: The Latest in Object Detection
- 🆕 YOLOv8.1 is out! The newest update in the YOLO series, maintaining its position as state-of-the-art for Object Detection, Instance Segmentation, and Classification.
⚠️ Main Challenge: Custom Dataset Preparation
- 🔍 Dataset Selection: Using Flickr27 as our image dataset.
- 📸 Flickr27 Overview: Contains 27 different brand logos, perfect for training YOLO on custom data.
- 💼 Custom Dataset Prep: The most crucial step in training YOLO models.
- 🛠️ Get Ready to Train: With YOLOv8.1 and Flickr27, you'll be well-equipped to handle custom object detection tasks!

Image Classification Matrix
Comparing inference latency, parameter footprint, and top-1 accuracy across modern vision architectures.
🚀 Exploring Image Classification Models with Transfer Learning!
- 🆕 Models Evaluated: We've assessed the following state-of-the-art models using the Flickr27 dataset:
- Xception ☕
- InceptionV3 🌈
- MobileNetV2 📱
- EfficientNet ⚡
🔍 Performance Aspects Compared
- ⚡ Inference Time: How quickly each model makes predictions.
- 📦 Model Size: The storage requirements of each model.
- 🔢 Number of Parameters: The complexity and capacity of each model.
- 📈 Accuracy: How well each model performs in classifying images.
- 🏷️ Predicted Class: The class each model predicts for the input images.
- 📚 Understanding Trade-Offs: These comparisons will help us understand the trade-offs between speed, efficiency, and accuracy for each model.
💡 You can train your own model on any dataset following the link below:
Train Your Model
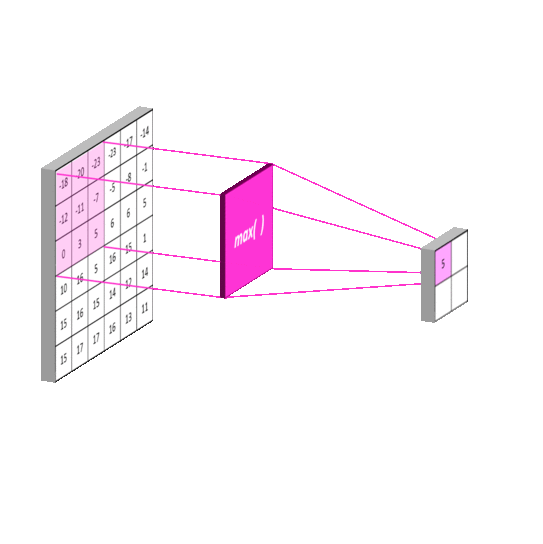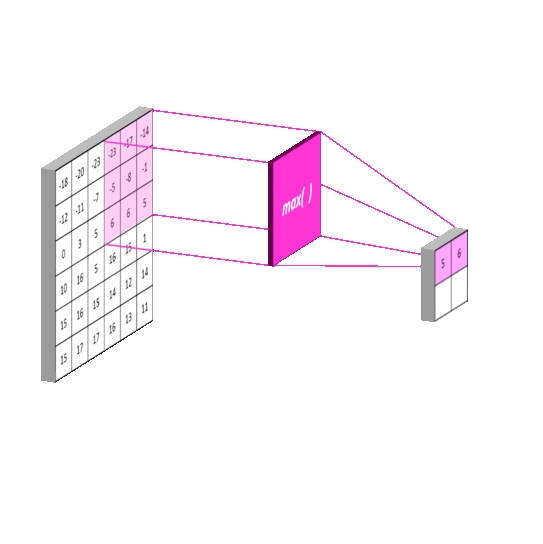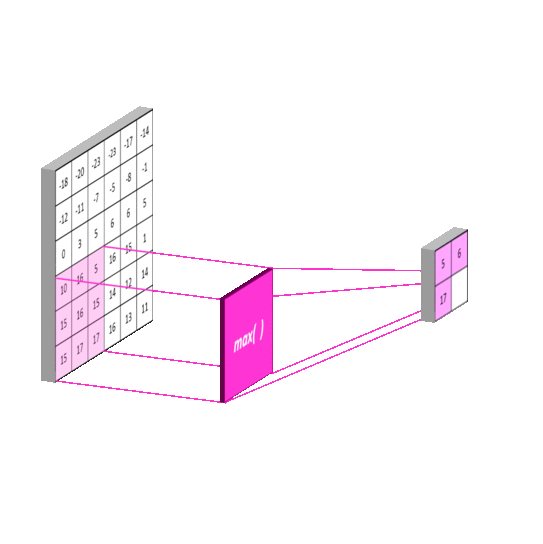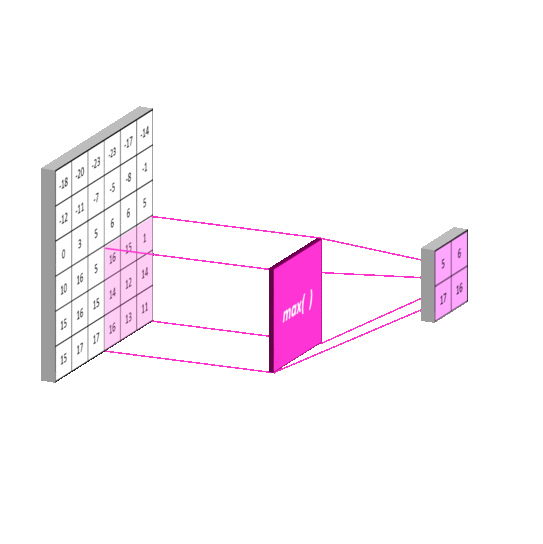
🚀 To see How it works..
Clustering Playground
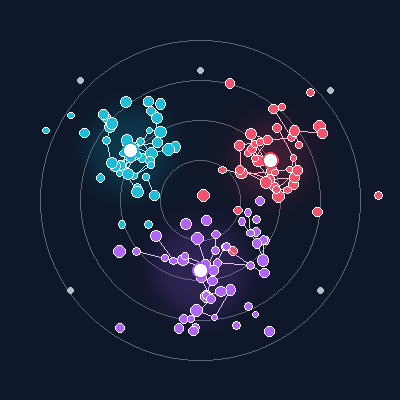
Explore dataset partitioning via K-Means and density-based spatial clustering (DBSCAN).
Connect & Collaborate
Connect with me across platforms, explore open-source code repositories, or read my technical publications.
Connect with me across platforms, view my open-source code repositories, or read my technical AI/ML publications:
GitHub Stats
User Authentication
PostgreSQL JWT Bearer Authentication and persistent session checkpointing.